19 Aug 2026 · 5 min read
agentic coding
750 Tokens/Second: What Cerebras' Wafer-Scale Inference Actually Changes for Agent UX
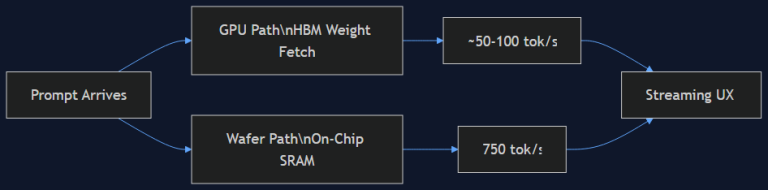
OpenAI's GPT-5.6 Sol Ultrafast, powered by Cerebras' Wafer-Scale Engine, hits 750 output tokens/second — 14x standard inference. I dug into why on-chip SRAM beats HBM for this, and what it means for how we design latency-sensitive agent products.
Read more