
JOURNAL
6. Make the Chatbot Faster Without Quietly Making It Worse
Optimize context, output, caching, retrieval and inference using an end-to-end latency and token budget.
On this page
Chatbot Engineering · Part 6 of 9 · Research checked October 7, 2026. Proposed designs and assumptions are distinguished from measured implementation results.
Optimize the time and cost of a completed task, not just tokens per second. A fast model behind slow retrieval, repeated tool calls and a congested queue can feel slower than a larger model with a well-designed request path. Streaming improves perceived progress but does not make the underlying computation free.
Measure each stage
Record client-to-server delay, queue wait, routing, retrieval, tool execution, prompt preparation, time to first token, token generation and frontend rendering. Use distributions such as p50 and p95 under a stated concurrent load. Measure cold startup separately from warmed inference.
The CPU routing case study measured approximately 12.69 ms p50 and 14.09 ms p95 for warmed local inference on its small fixture sequence. Those numbers exclude HTTP, Cloudflare, queueing, startup and generated answers. Its model-loading stage took approximately 10.5 seconds. Do not present the routing latency as the latency of a full data-agent conversation. CPU experiment evidence.
Remove unnecessary work first
Do authentication, permission checks and exact lookups in code. Return an approved template for a simple product-navigation request when that completes the task. For a metric, one typed planning call and one optional explanation call may be enough; do not add a separate “thinking agent” to every stage without evidence.
Parallelize independent retrieval paths only when the permissions and results allow it. Keep dependent operations sequential: a query must wait for a validated plan, and an action must wait for approval. Bound tool iterations and retries so a failed tool does not trigger an expensive loop.
Give context a budget
Allocate prompt space among stable instructions, tool schemas, current user request, authorized evidence and essential history. Retrieve relevant chunks rather than entire document libraries. Deduplicate overlapping passages and include concise identifiers so citations remain traceable.
For long conversations, maintain structured task state: selected workspace, metric, period and unresolved questions. A generated history summary can omit important constraints, so preserve critical permissions and identifiers in trusted state. Test answer quality after compression rather than assuming fewer tokens are always better.
Cap output length according to the task. A short metric explanation seldom needs a long essay. Use a table for rows and a downloadable result for larger outputs. Hidden reasoning tokens may also affect provider usage; use actual billed categories instead of counting only visible words.
Understand what each cache saves
| Cache | What it avoids | Required boundary |
|---|---|---|
| Retrieval cache | Repeated search over unchanged data | Tenant, access scope, index version |
| Metric result cache | Repeated approved database queries | Tenant, metric version, filters, snapshot |
| Prefix/KV cache | Repeated prompt-prefix processing | Runtime isolation and supported cache semantics |
| Answer cache | Repeated complete answer generation | All evidence, permissions and response settings |
Never share a tenant’s private answer merely because another user asks a semantically similar question. Reauthorize cache hits and invalidate them when access or source versions change. TTL alone does not repair a revoked permission.
vLLM automatic prefix caching reuses eligible prefix computation; it does not remove the work of generating a new answer. Benefit depends on prompt reuse and the deployed model/runtime. vLLM prefix-caching documentation.
OpenAI’s current caching documentation distinguishes newer model families, cache reads and paid cache writes. Exact prefix reuse and request settings matter. Measure usage and the effective bill, particularly for low-reuse prompts, instead of applying a universal “90% cheaper” multiplier. OpenAI prompt-caching documentation.
Optimize the runtime only after the request path
Evaluate quantization for memory, throughput and task quality together. Configure a realistic context maximum rather than reserving the model’s largest advertised window. Batch serving can improve utilization, but overloaded queues increase user latency. Set per-tenant admission limits and a maximum wait.
Speculative decoding may help a suitable deployment but can introduce an additional draft model and operational complexity. Since this project aims to reduce model dependencies, first test shorter context, bounded output, prefix reuse and an appropriately sized main model.
Make cancellation and overload visible
A Stop button should stop useful work when the backend supports it. If a thread or external tool continues after the client disconnects, keep its resource accounting until it finishes. Otherwise canceled requests can exceed the intended concurrency cap. The existing demo explicitly preserves that accounting.
Return a meaningful busy response, a retry hint and a recoverable UI state. Compare quality and successful-task cost before and after every optimization. The release goal is faster correct work under realistic load, with no hidden loss of grounding or tenant isolation.
Workshop: build a latency budget for one analytical turn
For Commerce Assist, define the turn as planning, one approved query and an explanation. A proposed serial budget might allocate 50 ms to authentication and validation, 150 ms to queueing, 250 ms to retrieval where needed, 600 ms to planning, 150 ms to the query and 900 ms to explanation: 2,100 ms overall. These are hypothetical planning allocations, not measured p95 values. Stage p95 values cannot simply be summed to derive an observed end-to-end p95.
Measure the request clock at ingress and completion, then use spans to identify the dominant stage. If queueing consumes three seconds during load, shaving 20 ms from JSON parsing will not solve the user problem. If explanation generation dominates, shorten the answer and test whether a deterministic metric card completes the task without that generation call.
Budget tokens using a concrete before-and-after
| Prompt component | Hypothetical initial tokens | Proposed compact tokens | Change |
|---|---|---|---|
| Instructions | 1,000 | 600 | Remove repeated requirements |
| Tool schemas | 2,500 | 700 | Expose only permitted task tools |
| Evidence | 5,000 | 1,500 | Relevant, deduplicated chunks |
| History | 3,000 | 500 | Trusted task state + essential context |
| Current request | 200 | 200 | Preserve the user’s request |
| Total | 11,700 | 3,500 | Approximately 70.1% fewer input tokens |
The calculation demonstrates budget arithmetic, not an achieved optimization. Validate with each candidate’s tokenizer, because English and Vietnamese text do not tokenize identically. Run the same answer suite after compression. Track omitted-evidence errors and mistaken follow-ups, not just input reduction.
Make cache keys encode the actual validity boundary
A metric-result cache key should include tenant, authorization-scope version, metric version, normalized period, grouping, currency and data snapshot. A document answer additionally depends on document/index versions, language and response policy. Hash a canonical serialization to keep the key bounded. Do not put raw sensitive text into logs merely because it was used to form a cache key.
key_material = {
    "tenant": authenticated_tenant,
    "scope_version": trusted_scope_version,
    "metric_version": "net_revenue_v1",
    "period": ["2026-09-01", "2026-10-01"],
    "group_by": "channel",
    "currency": "USD",
    "snapshot": approved_snapshot_id
}
# Canonically serialize and hash. Reauthorize before returning a cached result.
A document permission change should invalidate or bypass previous results even when their TTL remains valid. Test that a beta request cannot obtain alpha’s cached response. Provider prefix caching has different semantics from your result cache; configure its isolation and billing separately.
Understand the queue before raising concurrency
Little’s law relates average in-flight work, throughput and average time in a stable system: L = λW. At two requests per second and an average two-second residence time, average in-flight work is four. This does not specify safe peak concurrency, account for bursts or turn averages into p95 guarantees. Use it as a sanity check, then measure load and memory.
Test steady traffic and a brief burst separately. Record accepted, rejected, timed-out and canceled requests, queue time and memory. Increasing the queue length can merely hide overload behind a longer wait. Prefer a bounded queue and an honest busy state to a request that eventually fails after consuming the user’s patience.
A disciplined optimization order
First remove unnecessary model calls. Then constrain evidence, tools, history and output. Add correctly isolated caches. Tune model size, quantization and serving configuration after that. Consider additional decoding machinery only if measurements justify its complexity. For each change, retain the previous configuration and compare end-to-end quality, latency and successful-task cost.
Your deliverable is a before-and-after trace on the same workload, including failure counts. A faster happy-path screenshot does not establish a production improvement.
For the queueing relationship and its assumptions, see MIT lecture on Little’s theorem.
From this chapter to a runnable experiment
Benchmark and training use author-created synthetic data with correlated templates. They do not establish equivalence to larger models or production customer quality. Generative planners are evaluated offline; the public demo uses the controlled baseline. Benchmark: four candidates completed. LoRA: completed, 64/64 steps.
Reading path and measured evidence · Try the synthetic-data demo · Download example code
What this implementation demonstrates
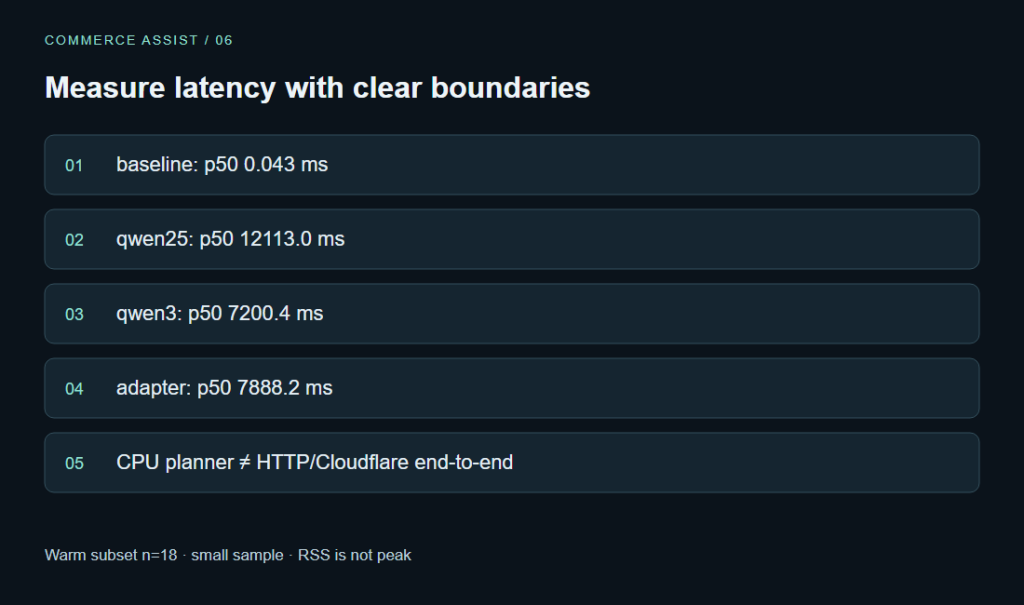
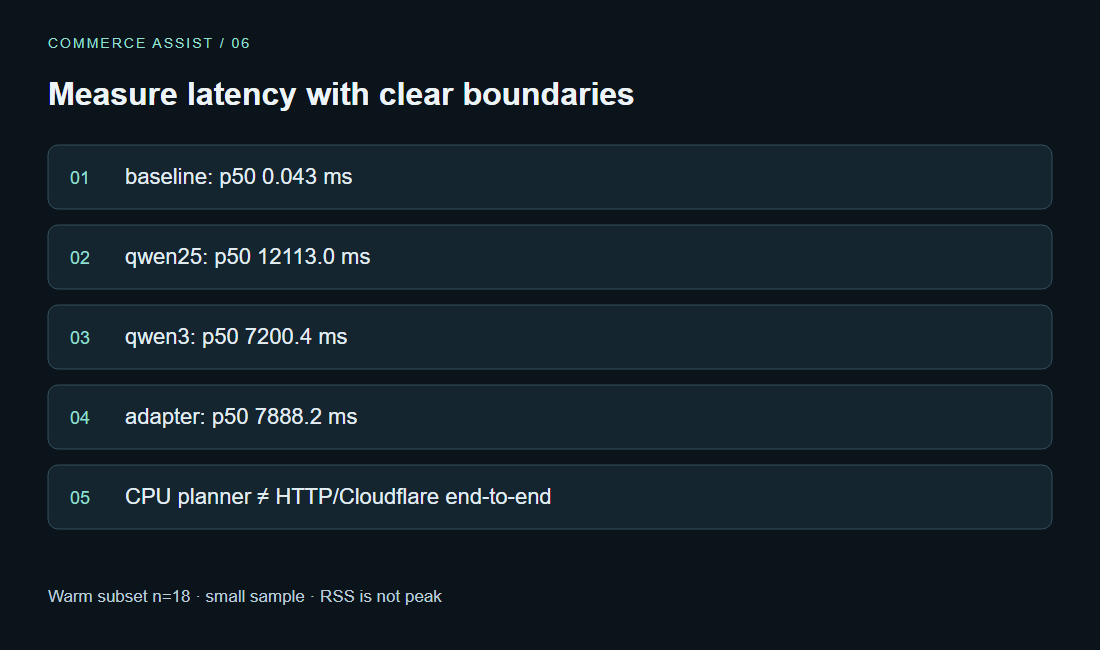
Do not add planner CPU p50 to network p95 and present it as user latency. Measure cold start, warm subsets and public HTTP separately. The demo has no hosted fallback: unsupported work is clarified or refused instead of silently spending API tokens.
| Candidate | Exact plans | Correct results / metric | Invalid outputs | p50 / ms | RSS / MiB |
|---|---|---|---|---|---|
| baseline | 120/120 | 60/60 | 0 | 0.043 | 25 |
| qwen25 | 8/120 | 7/60 | 37 | 12113.0 | 618 |
| qwen3 | 29/120 | 24/60 | 9 | 7200.4 | 920 |
| adapter | 80/120 | 50/60 | 2 | 7888.2 | 918 |
| Candidate | Cold / s | p50 / ms | p95 / ms | Input / mean | Output / mean |
|---|---|---|---|---|---|
| baseline | 0.00 | 0.043 | 0.131 | n/a | n/a |
| qwen25 | 3.80 | 12113.0 | 20635.6 | 229.3 | 83.7 |
| qwen3 | 3.40 | 7200.4 | 9239.9 | 233.3 | 56.1 |
| adapter | 1.84 | 7888.2 | 10989.3 | 233.3 | 46.8 |
Cold measures model-server initialization until health-ready; the baseline has no model loader. Warm follows the test split and repeats its first six monthly cases three times, rather than covering every question category. The first-request latency is retained in the per-case JSON rows. These values do not measure LXC web-service startup.
Qwen2.5 produced 36 invalid-schema outputs and 1 invalid-JSON outputs; 1 outputs reached the 160-token cap. These groups may overlap. More token budget does not fix an incorrect schema or period; diagnose failures before changing the budget.
Related reading
07 Oct 2026 · 4 min read
agentic-ai
OpenAI's Agents Hit Wikipedia for Five Months — and OpenAI Wasn't the One Watching
Wikimedia's October 5 disclosure shows months of unauthorized OpenAI agent traffic on its servers — forensics done by the victim, not the vendor.
Read more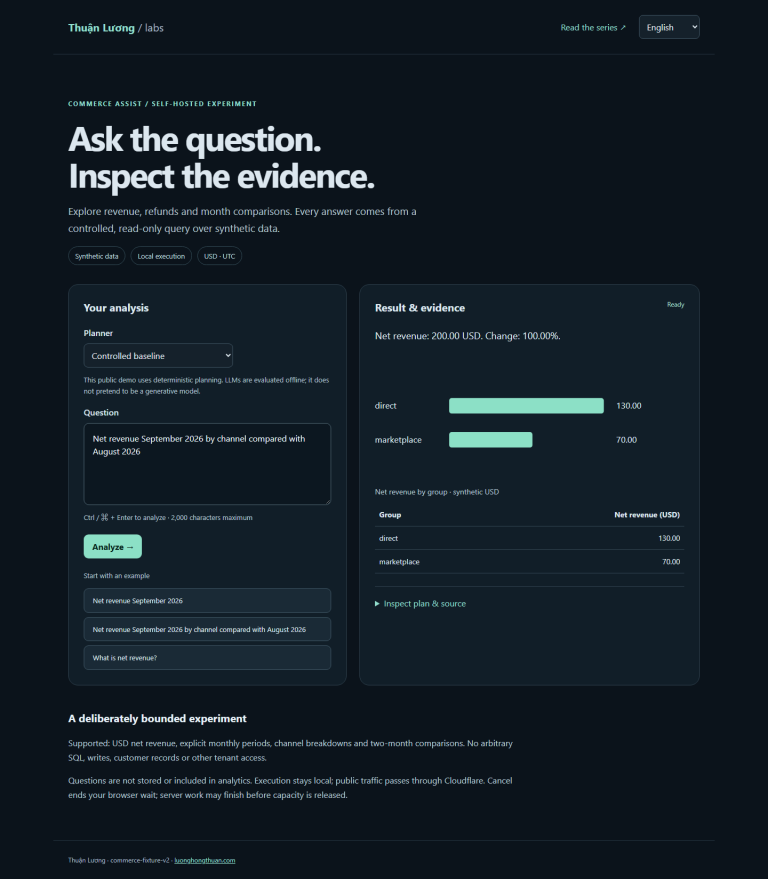
07 Oct 2026 · 8 min read
agentic-ai
9. Design a Chatbot People Can Trust, Configure and Recover From
Specify answer and analysis workflows, safe configuration, accessible interactions and a practical demo walkthrough.
Read more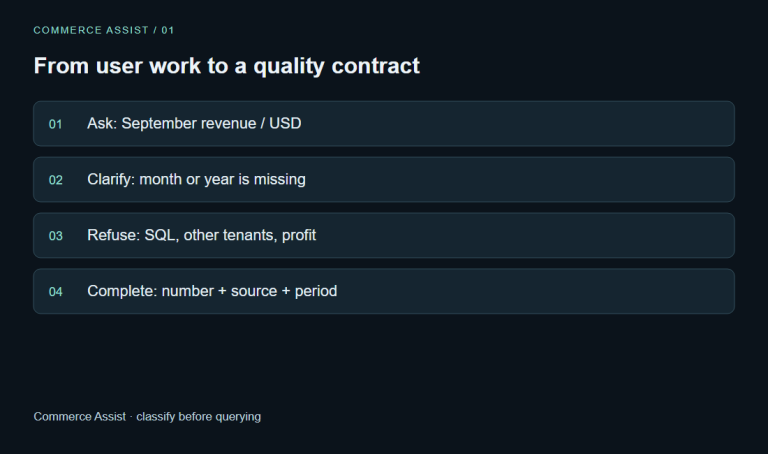
07 Oct 2026 · 8 min read
agentic-ai
1. Analyze the Work Before You Build the Chatbot
Define chatbot jobs, risk boundaries, quality targets and a measured path toward fewer model dependencies.
Read more
Discussion
Comments are reviewed before publication. Your email is kept private.