
JOURNAL
The Hive Playbook — five workflows that turned my agent platform into a team
I self-hosted an agent platform on hardware I already own. The models were never the hard part. The hard part was the playbook: the exact combinations of engine, tools, and surface that turn one platform into a coder, a researcher, a QA gate, and a business analyst. Here are the five I actually run.
On this page
I run a self-hosted agent platform called Hive on hardware I already own — a few Proxmox containers, a couple of Apple Silicon boxes, and a proxy that fronts every model behind one OpenAI-compatible endpoint. People assume the interesting part is the models. It isn’t. The interesting part is the playbook: the small set of repeatable combinations that turn the same platform into five different specialists.
A chat box with an LLM behind it is a toy. It can talk about your pull request but not review it, describe a test plan but not run it. What made Hive stick wasn’t a smarter model — it was giving agents hands, and then learning which hands to give which agent. Here’s the whole playbook.
Two choices, then Lego
Every workflow is two decisions.
Engine. Fast is a tool-loop — the model calls a tool, reads the result, calls another, answers. Bounded and cheap; use it when you know the shape of the task. Smart is the Claude Agent SDK running autonomously — it plans, takes many steps, and figures out what you didn’t specify. Fast for “do this,” smart for “figure this out.”
Surface. Chat is interactive. Origin is a kanban of autonomous runs — assign a card, walk away. Automation fires an agent on a schedule, a webhook, or a Telegram message.
Pick an engine, give it tools, choose a surface. Everything below is that.
1. Coding — three gears
The mistake is using the heaviest gear for everything.
- Chat: a fast agent with
run_code(sandboxed execution) andrun_tests(clones a repo, auto-detectsnpm/pytest/go/make, runs it) for snippets and “are the tests green?”. - Dispatch:
cursor_codehands a task to a Cursor Cloud Agent that clones the repo, edits, and opens a PR — a drive-by change while I keep chatting. - Autonomous: Origin with the smart harness clones the repo, plans, implements, tests, self-reviews, and opens the PR, streaming each step to a timeline.
Then the loop closes: a reviewer agent runs pr_review (breaks the PR description into claims,
verifies each against the diff) and posts the verdict with github_pr_review — approve and label
qa-pass, or request changes with specifics.
2. Research — with a tail
Research is worthless if it evaporates into a chat nobody reads again.
A fast agent with web_search, fetch_url, and wikipedia gathers; a harness rule — research
first, cite, then answer — keeps it honest. Big questions go to the smart engine, which plans its
own search path. The tail is the point: save_knowledge / save_context write findings into a
shared knowledge base with semantic retrieval, so every agent with search_knowledge recalls them
forever. Throwaway chats become institutional memory.
3. QC — including the agents
Two targets: the code, and the agents.
run_tests is the cheap gate. The one that changed how much I trust a deploy is browser_agent —
it drives a real Chromium: navigate, click, type, fill forms, log into web apps. Credentials come
from Vaultwarden (the model never sees the password) and a persistent session keeps it logged in
across steps. “Log in, create an order, confirm the total, screenshot it” runs against the actual
preview. A defect becomes a github_create_issue with the failing screenshot.
And the agents drift the moment you touch a harness — so an eval harness pins behaviour with golden sets and runs on every save. Evals are unit tests for prompts. QC that skips the agents has a blind spot.
4. BA — the output is a file
This is where a chat box’s missing hands hurt most, and where tools pay off most, because the output is a document someone opens.
The agent gathers — calendar, recent_emails, search_knowledge — then save_context to lock
the picture in. Then it writes the deliverables: generate_docx (markdown → Word BRD),
generate_pptx (outline → stakeholder deck), generate_xlsx (JSON → backlog / requirements
matrix), each a download link. Finally github_create_issue or Linear (over MCP) turns each
requirement into a ticket. Discovery to backlog — spec, deck, and tickets — in one conversation.
5. Ops — the quiet workhorse
A smart agent with bash and read-only creds is an auditor (my read-only AWS auditor is the
template: run real commands, show real output, never attempt a blocked write). Lighter checks use a
fast agent with http_request (which refuses internal addresses). Any agent goes unattended via a
scheduled trigger, webhook, or Telegram message, with results pushed back by telegram_send.
The composition is the point
No agent here is impressive alone. The value is the fabric between them: research feeds the KB, a BA agent reads it and writes the BRD, Origin implements the spec, a QA agent browser-tests the preview, a reviewer approves the PR. Each step is a narrow specialist doing one thing well.
That’s the lesson from building it: don’t chase one omniscient assistant — that’s the chat-box trap in a bigger box. Build a toolbox of narrow specialists and a fabric that connects them. You rent the model; you build the playbook. The playbook is where the leverage lives.
Related reading
· 8 min read
agentic-ai
1. Analyze the Work Before You Build the Chatbot
Define chatbot jobs, risk boundaries, quality targets and a measured path toward fewer model dependencies.
Read more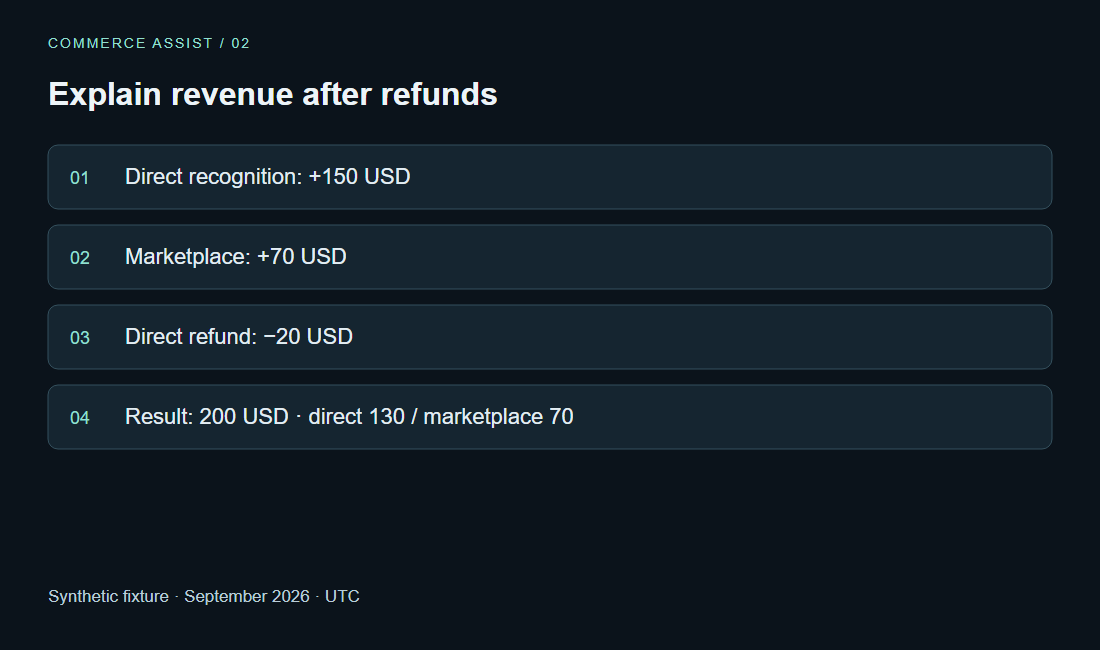
· 10 min read
agentic-ai
2. Build a Data Agent That Can Explain Its Numbers
Design a governed data agent with a semantic layer, read-only tools, tenant isolation and verifiable answers.
Read more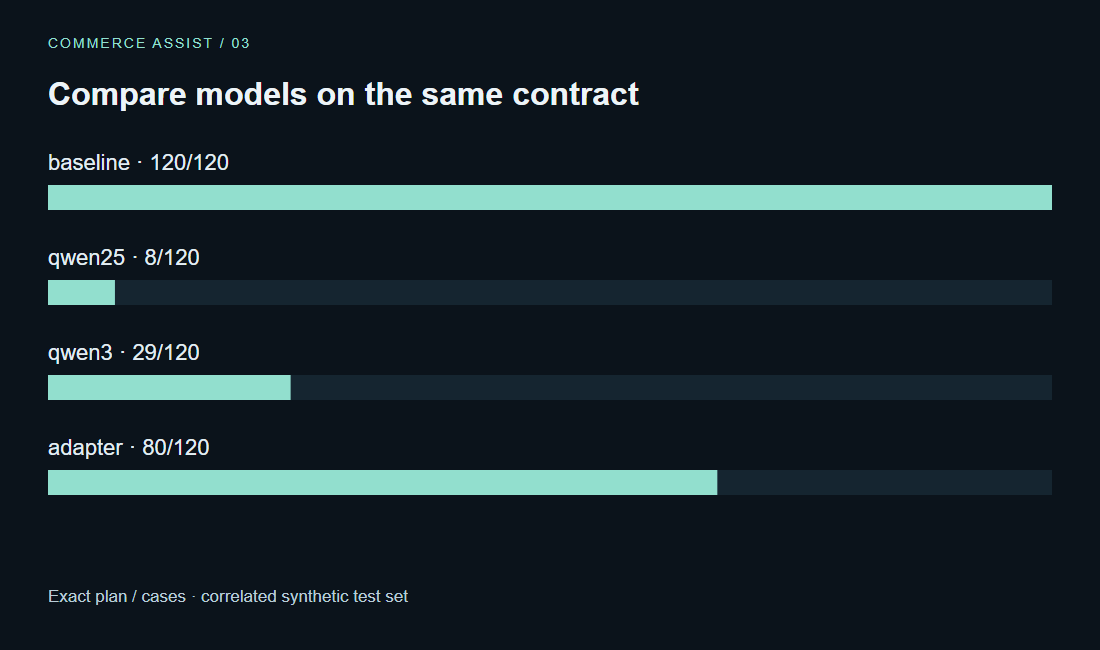
· 8 min read
agentic-ai
3. Choose a Chatbot Model You Can Actually Operate and Train
Compare practical local model candidates, CPU routing and GPU fine-tuning without confusing size with production quality.
Read more
Discussion
Comments are reviewed before publication. Your email is kept private.