
JOURNAL
Qwen3.8-Flash-Next Beats Opus 4.6 on Agent Benchmarks With 6B Active Params — I Ran the Numbers
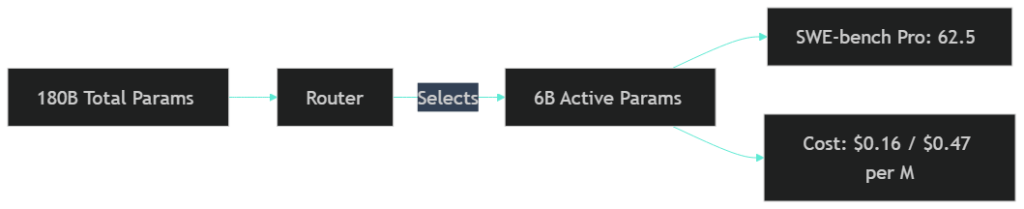
Alibaba's Qwen3.8-Flash-Next, an early preview of Qwen4's architecture, scores 62.5 on SWE-bench Pro against Claude Opus 4.6 Max's 53.4 — while activating just 6B of its 180B parameters. Here's what the routing architecture actually buys you, and where the benchmark story gets more complicated.
On this page
Alibaba’s Qwen team released Qwen3.8-Flash-Next on August 26, and the headline number is the kind that makes you re-check the source: 62.5 on SWE-bench Pro, ahead of Claude Opus 4.6 Max’s 53.4, Qwen3.8-27B’s 61.7, and DeepSeek-V4-Flash’s 56.0 — while activating only 6 billion of its 180 billion total parameters per token. Alibaba is explicit that this isn’t just another cost-tier release; it’s described as an early preview of the architecture behind the upcoming Qwen4 family. I spent an evening reading the technical report and running a self-hosting cost model against my own agent workload, because a benchmark table alone doesn’t tell you whether a model is actually a fit.
The architecture: why 6B active can beat models 10x its active size
Qwen3.8-Flash-Next is a Mixture-of-Experts model — 125B main-model parameters, 51B in N-gram embeddings, 180B total, but a router selects only 6B active parameters per forward pass. What’s new relative to the last generation is the attention layer: a hybrid combining Gated DeltaNet (a linear-attention variant) with Qwen Sparse Attention, plus gated residual branches and an updated Muon optimizer setup for training stability at this sparsity level.
Qwen3.8-Flash-Next forward pass, per token:
  Total params:      180B  (125B main + 51B embedding)
  Router selects:     6B active experts
  Attention:          Gated DeltaNet (linear, local) + Sparse Attention (global)
  Result:             frontier-adjacent quality at a fraction of the compute
The practical reason this matters: inference cost and latency scale with active parameters, not total parameters. A 6B-active model can run on hardware that would choke on a dense 180B model, while the router still gives it access to a much larger effective knowledge base than a genuinely dense 6B model would have. This is the same MoE bet several labs have made this year, but the benchmark gap here — beating a Claude Opus-class model on SWE-bench Pro and CoWorkBench — is large enough that it’s worth taking seriously rather than dismissing as another “beats GPT-4 on a cherry-picked eval” claim.
Reading the benchmark gap honestly
Before I get excited: SWE-bench Pro and CoWorkBench are agentic coding and multi-step task benchmarks, and Qwen’s own team ran and reported these numbers. The comparison point — Claude Opus 4.6 Max — is also not Anthropic’s current frontier model by the time you’re reading this, so “beats Opus 4.6” is a real result but a moving target, not a permanent claim. The JobBench gap is the most eyebrow-raising number (55.7 vs 36.6), and that’s exactly the kind of gap I’d want to verify against my own task distribution before trusting — big swings on benchmarks I haven’t personally stress-tested are the first thing I discount when evaluating a new model, not the first thing I repeat.
What I do trust without further verification: the architectural efficiency claim. 6B active parameters producing this quality tier is a compute-efficiency result that doesn’t depend on trusting Qwen’s benchmark methodology — it’s a direct consequence of the MoE + hybrid attention design, and it’s independently verifiable by anyone who self-hosts the weights.
Running the self-hosting math
Pricing on the hosted API is $0.16 input / $0.47 output per million tokens — competitive, but the more interesting number for a Tech Lead evaluating build-vs-buy is the self-hosting profile. FP8 weights are 172.78 GiB, so this needs a multi-GPU node, not a single card, but it’s a realistic target for a team already running inference infrastructure. Weights are on Hugging Face and work with Transformers, vLLM, SGLang, and Docker Model Runner out of the box.
# rough self-host vs API math for an agentic coding workload
# assumptions: team of 8 engineers, moderate agent usage
monthly_tokens_in = 600_000_000   # 600M input tokens/month (large context, tool outputs)
monthly_tokens_out = 60_000_000   # 60M output tokens/month

api_cost = (monthly_tokens_in / 1e6 * 0.16) + (monthly_tokens_out / 1e6 * 0.47)
# = $96 + $28.2 = ~$124/month at this volume -- API wins easily here

# self-hosting only starts to make sense once:
# 1. volume is 15-20x higher (multi-team platform usage, not one squad), OR
# 2. data residency/compliance rules out the hosted API regardless of cost, OR
# 3. you already run GPU infra for other inference and marginal cost is low
That’s the honest crossover: at team-level usage, the hosted API is cheaper and simpler than standing up multi-GPU inference for a 172GB weight set. Self-hosting becomes the right call at platform scale or when compliance forces the decision, not as a default optimization.
Where I’d actually route work to this model
Given the SWE-bench Pro and CoWorkBench numbers, I’d pilot Qwen3.8-Flash-Next for structured, tool-using coding agent tasks — PR generation, test writing, scoped refactors — where I can measure success against my own eval set rather than trusting the published numbers. I would not swap it in blind for open-ended architectural reasoning or judgment-heavy tasks where Opus-class or Sonnet-class models have a longer track record on my specific workloads. The efficiency story is real and independently verifiable; the “beats frontier models” framing needs your own eval harness before it changes what you route production traffic to.
Takeaway
The 6B-active-parameter number is the part of this release I’d actually build a decision around — it’s a verifiable architectural fact, not a benchmark claim, and it changes the self-hosting math meaningfully versus a dense model of comparable quality. The SWE-bench Pro headline is worth testing on your own tasks before you trust it, but the underlying MoE-plus-hybrid-attention efficiency gain is the real signal here, and it’s a preview of where Qwen4 — and probably the next generation of every major lab’s MoE line — is heading.
Sources: The New Stack: Qwen3.8-Flash Previews Qwen4, MarkTechPost: Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next, officechai: Alibaba Releases Qwen 3.8 Flash-Next, Beats Opus 4.6 On Most Benchmarks
Related reading
· 15 min read
ai
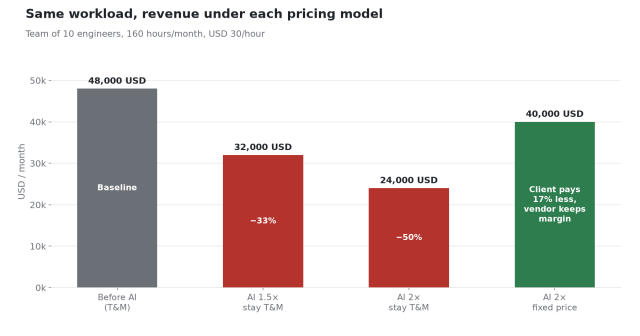
When AI makes code cheap: why the billable-hour model of software outsourcing is being torn down and rebuilt
AI makes an hour of coding worth more but makes billing by the hour worth less. The shift from T&M to outcome-based pricing, seen by CEOs, engineers, clients and investors.
Read more
· 4 min read
architecture
Talking About Chaos Engineering: Break It on Purpose
Learn the word 'inject' and the vocabulary engineers use to talk about chaos engineering, fault injection, and testing systems by breaking them on purpose.
Read more
· 5 min read
agentic-ai
Gemini 4 Hydrogen Is Google's Bet That Most Agent Work Doesn't Need the Flagship
Google's new mid-tier model runs 2.5x faster than Gemini 3.8 Flash and triples its Terminal-Bench score, while Antigravity Orchestrator hands it most of the actual agent work. Here's what the numbers mean for teams building on Gemini.
Read more
Discussion
Comments are reviewed before publication. Your email is kept private.