
JOURNAL
LLM Fine-Tuning in Production: A Tech Lead’s Practical Guide
When to fine-tune vs. prompt-engineer, which technique to pick in 2026 (LoRA, QLoRA, DPO), how to size your dataset, and how to wire the whole thing into a CI/CD quality gate that blocks regressions before they ship.
On this page
The question I get most from tech leads moving into AI work is not “which model should we use?” — it’s “when do we fine-tune, and what does that actually look like end-to-end?”
The short answer: fine-tune later than you think you should, but have the pipeline ready before you need it. Here’s the full picture.
When Fine-Tuning Is the Right Call
Start with prompt engineering. It’s cheaper, faster to iterate, and reversible. You should only move to fine-tuning when one of these is true:
- Consistent format requirements: You need structured JSON or a specific output schema every time, and prompting alone can’t enforce it reliably.
- Domain vocabulary: The base model keeps hallucinating domain-specific terms (medical codes, internal product names, legal clauses) that don’t appear in its training data.
- Latency budget: You’re paying for large context windows to stuff in examples. Fine-tuning bakes those examples into the weights, shrinking context and cutting inference cost.
- Behavior consistency: LLM-as-judge evals show variance above your tolerance threshold, and the root cause is the model not “speaking your style.”
A useful test: if 20 hand-written examples in the system prompt gets you 80% of the way to your quality target, fine-tuning the remaining gap with 500 curated examples is probably worth it. If the 20-example prompt gets you 20%, the problem is architecture, not fine-tuning.
The 2026 Technique Landscape
Three approaches dominate production fine-tuning this year:
LoRA (Low-Rank Adaptation) — instead of updating all model weights, you inject small rank-decomposition matrices into the attention layers and train only those. Memory usage drops by 90%+ versus full fine-tuning. On most classification and generation tasks it delivers 95–99% of full fine-tuning quality. Default choice when you have reasonable GPU headroom.
QLoRA — LoRA on a quantized base model. The base weights are frozen at 4-bit precision; the LoRA adapters train in 16-bit. A 13B model fine-tunes on a single A100. The open-source stack (Unsloth, BitsAndBytes, Hugging Face PEFT) treats this as the low-cost default in 2026.
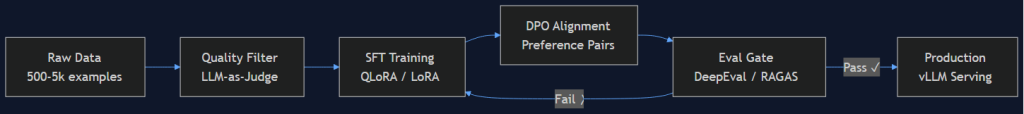
DPO (Direct Preference Optimization) — used after SFT (Supervised Fine-Tuning) to align outputs with human preferences. It’s replaced RLHF in most production teams because there’s no separate reward model, no PPO instability, and the math is a clean contrastive loss over preference pairs. The practical pipeline is: SFT first, then DPO on a curated preference dataset.
The typical production path: QLoRA on an 8B open-weight model (Llama 3.1, Mistral Nemo, Qwen 2.5), SFT on domain examples, DPO for alignment, vLLM for serving. Total compute cost under $50 for most tasks; one week of engineering for the first run.
Dataset Sizing — The Numbers That Actually Matter
2026 guidance has converged on these ranges:
| Task type | Minimum | Sweet spot |
|---|---|---|
| Classification / extraction | 200 | 500 |
| Content generation | 500 | 1,000–2,000 |
| Complex domain tasks | 1,000 | 3,000–5,000 |
Below 50–100 examples, you’re doing few-shot prompting disguised as fine-tuning — save the compute.
Quality beats quantity. 1,000 hand-curated examples consistently outperforms 100,000 noisy ones. The failure mode isn’t “not enough data” — it’s catastrophic forgetting, where training on a narrow dataset degrades general capabilities. Fix: include ~10–15% general-domain examples in your training set as a regularizer.
Synthetic data from a stronger teacher model (Claude Sonnet, GPT-4o) is now standard practice for bootstrapping. Generate 3–5× your target count, run it through a quality filter (an LLM-as-judge scoring relevance and accuracy against your rubric), keep the top third.
Wiring Fine-Tuning into CI/CD
Here’s where most teams drop the ball: they fine-tune manually, deploy manually, and discover regressions in production metrics three days later.
The pattern that works is treating your fine-tuning pipeline like a software release:
# .github/workflows/finetune-eval.yml
name: Fine-tune Eval Gate

on:
  push:
    paths:
      - 'training-data/**'
      - 'training-config/**'

jobs:
  eval:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4

      - name: Run eval suite
        run: |
          python scripts/run_evals.py \
            --model-checkpoint ${{ env.CANDIDATE_MODEL }} \
            --dataset evals/golden-set-v3.jsonl \
            --threshold-faithfulness 0.90 \
            --threshold-relevancy 0.85 \
            --fail-on-regression

      - name: Gate deployment
        if: steps.eval.outcome == 'failure'
        run: |
          echo "Eval gate FAILED — blocking deployment"
          exit 1
The key pieces:
- Version your training data alongside your model config. A git diff of
training-data/should tell you exactly what changed between runs. - Maintain a golden eval set — 100–200 examples with known-good answers, never included in training. Treat it like a test database: only add, never modify.
- Define numeric thresholds before you ship the first version. Faithfulness > 0.90, Answer Relevancy > 0.85, Context Precision > 0.80 are reasonable RAG starting points. Classification tasks use F1 or accuracy — pick one before training, not after.
- Track regressions, not just scores. A model that improves on the new task but drops 3 points on a capability it had before is a regression. Your eval gate needs to catch both.
Tools in 2026 that integrate well with this pattern: DeepEval (pytest plugin, open-source, CI-ready), Braintrust (blocks PR merges when scores drop), RAGAS (RAG-specific metrics). Pick one and own it — the worst outcome is three tools running different metrics with no single source of truth.
The Forgetting Problem
Catastrophic forgetting is underestimated in team discussions. I’ve seen a fine-tuned support bot that answered domain questions beautifully but completely lost the ability to handle simple arithmetic in tool-call responses. No one noticed until a customer complaint.
Practical mitigations:
- Mix general data in — 10–15% general-domain examples from the base model’s domain.
- LoRA instead of full fine-tuning — freezing most weights inherently limits forgetting.
- Eval breadth — your golden set should include examples from capabilities you care about preserving, not just the target task.
- Checkpoint comparison — before promoting a fine-tune, diff it against the base model on a broad capability benchmark (MMLU, GSM8K, your own regression suite).
A Realistic Timeline
Week 1: Data collection and cleaning. Minimum 500 curated examples. Set up your eval golden set in parallel — don’t wait until the model is trained.
Week 2: First training run (QLoRA, SFT only). Run evals. Expect 70–80% of target quality. Identify failure modes.
Week 3: DPO on preference pairs, targeted data augmentation for failure modes. Second eval run.
Week 4: Wire into CI, set thresholds, deploy to staging. Run shadow traffic against production baseline.
Week 5+: Iterate on data quality. The model doesn’t improve much after this point without more data or a different architecture.
What Not to Fine-Tune
A few things I’ve seen teams fine-tune when they shouldn’t:
- Reasoning ability — fine-tuning on reasoning examples usually overfits to the format, not the reasoning. Use a model with strong base reasoning and prompt it better.
- Tool-calling schemas — the base models have strong tool-calling capabilities. A few examples in the system prompt are almost always sufficient.
- Safety behaviors — removing refusals or restrictions via fine-tuning is a governance disaster waiting to happen. Use your own safety layer on top.
The Right Mental Model
Think of fine-tuning like a schema migration: you make a targeted change, run the tests, and if the tests pass you promote. You don’t manually inspect every row.
The teams I see succeed with fine-tuning in production have three things in common: they built the eval pipeline before they needed it, they treat training data as a first-class engineering artifact, and they define “good enough” numerically before the first training run. Everything else is implementation detail.
Sources:
Related reading
· 15 min read
ai
When AI makes code cheap: why the billable-hour model of software outsourcing is being torn down and rebuilt
AI makes an hour of coding worth more but makes billing by the hour worth less. The shift from T&M to outcome-based pricing, seen by CEOs, engineers, clients and investors.
Read more
· 5 min read
agentic-ai
Gemini 4 Hydrogen Is Google's Bet That Most Agent Work Doesn't Need the Flagship
Google's new mid-tier model runs 2.5x faster than Gemini 3.8 Flash and triples its Terminal-Bench score, while Antigravity Orchestrator hands it most of the actual agent work. Here's what the numbers mean for teams building on Gemini.
Read more
· 5 min read
ai-infrastructure
Railway's October Breach Shows What AI Inference Fraud Actually Looks Like
A misconfigured OIDC trust binding plus a build-isolation escape let an attacker decrypt 1,852 users' provider tokens and run roughly $740,000 in AI inference fraud in about 26 hours. Railway's own incident report has the timeline.
Read more
Discussion
Comments are reviewed before publication. Your email is kept private.