· 4 min read
career-growth
English Lesson — Friday Morning: Career & Growth Vocabulary
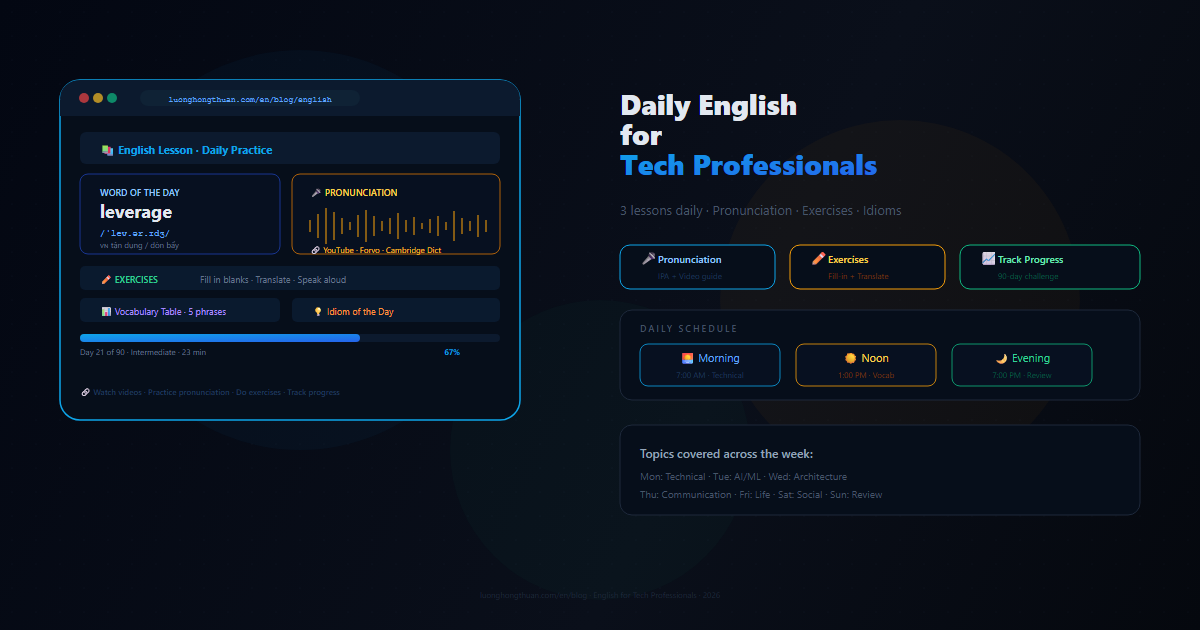
Daily English practice for tech professionals. Morning session covering career growth with pronunciation guide, exercises, and real-world examples.
Read moreIDEAS, DECISIONS & LESSONS
Notes on AI, architecture and building useful products.
1,005 articles
· 4 min read
career-growth
Daily English practice for tech professionals. Morning session covering career growth with pronunciation guide, exercises, and real-world examples.
Read more· 4 min read
agentic coding
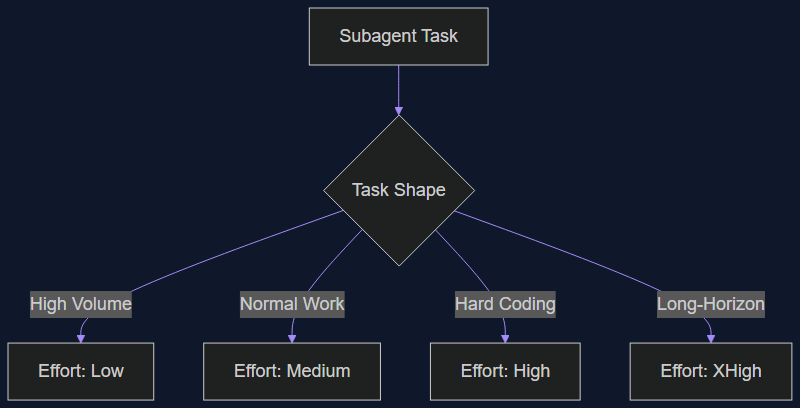
Opus 5 shipped a five-level effort parameter, and Claude Code now lets every subagent set its own model and effort in frontmatter. A practical guide to mapping your agent fleet to a cost curve instead of a flat rate.
Read more· 3 min read
english-lesson
Word of the day: facilitate. Learn the vocabulary for running focused meetings, keeping discussions on topic, and moving a group toward a decision.
Read more· 4 min read
ai
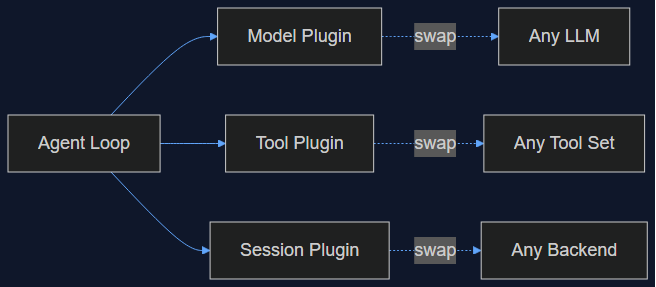
DeepSeek open-sourced an agent harness where the model, tools, memory, and even the loop itself are swappable plugins. A hands-on look at the pattern and how to apply it to your own agent stack.
Read more· 4 min read
ai
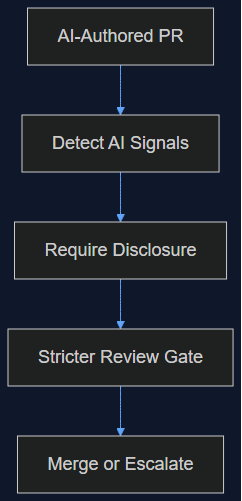
A Peking University study found coding agents ignore open-source contribution guidelines even with reminders. Here's a governance framework that relies on gates, not policy text, for engineering teams accepting AI-generated contributions.
Read more· 5 min read
architecture
Daily English practice for tech professionals. Morning session covering backpressure, dead letter queue, control plane, canary deployment, and tail latency with pronunciation guide, exercises, and real-world examples.
Read more· 4 min read
ai-agents
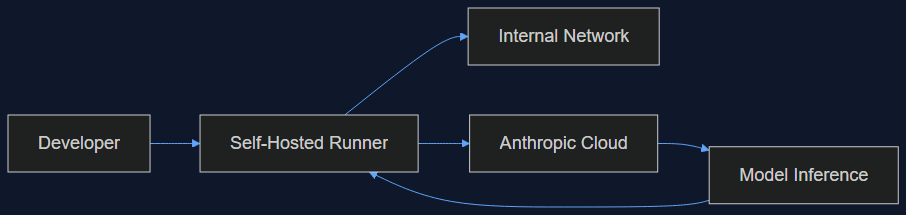
Anthropic's new self-hosted Claude Code beta lets sessions run on your own infrastructure with internal network access. Here's the rollout playbook — and the compliance gap most teams will miss: prompts still leave your network.
Read more· 4 min read
ai-agents
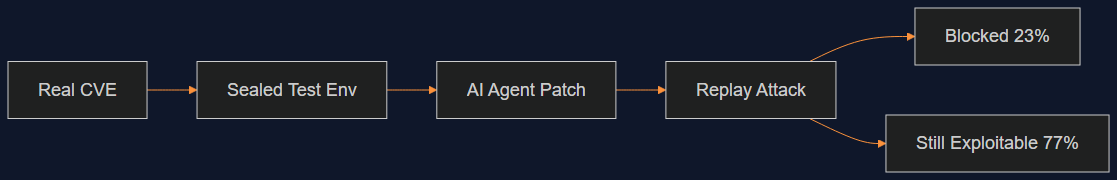
Innodata's new AI Cyber Training Suite benchmarks coding agents against real CVEs replayed in sealed environments. The best open-weight models fixed 23% of flaws unguided. Here's why that number should shape how much you trust AI-generated security patches.
Read more· 5 min read
agentic coding
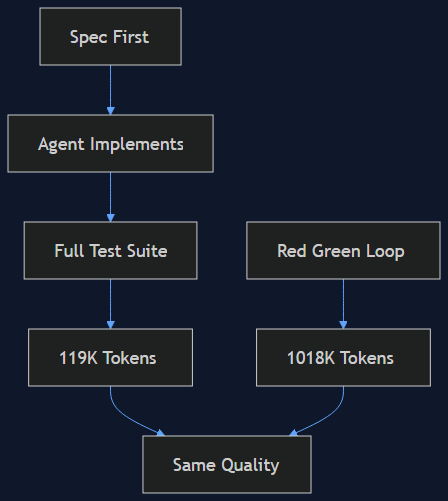
Thoughtworks ran a controlled experiment on TDD inside an AI agent loop: red-green cycles cost up to 8.5x more tokens than spec-first prompting, and blind quality judging preferred the non-TDD output. Here's what that means for how you should actually prompt coding agents.
Read moreLooking for an article, exploring a product, or starting an AI project?