30 Aug 2026 · 5 min read
ai
GLM-5.3-Flash: The First Open-Weight Model I'd Actually Trust With a 1M-Token Context
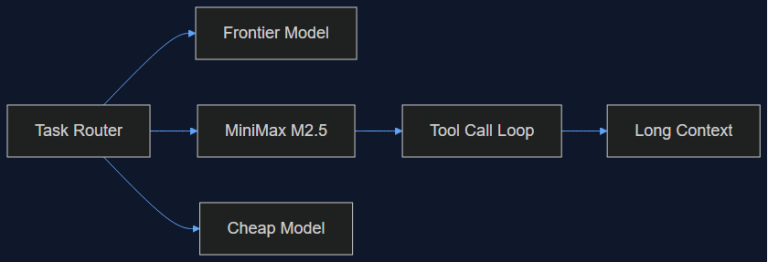
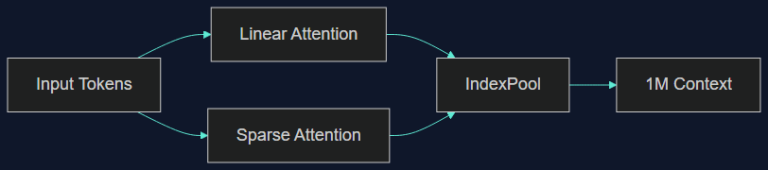
Z.ai's MIT-licensed GLM-5.3-Flash pairs a 320B-A18B MoE with a hybrid linear/sparse attention scheme built specifically to make million-token context usable, not just possible. A technical lead's read on IndexPool, the self-hosting math, and where it fits next to closed frontier models.
Read more