
JOURNAL
Claude Haiku 5.5 and the Real Math Behind Cheap Model Routing
Haiku 5.5 is 75% cheaper and far sharper at agent tasks, but a token-efficiency tax means the real savings aren't the headline number.
On this page
Anthropic shipped Claude Haiku 5.5 on October 7, 2026, and the number that actually matters if you run agent loops at volume is buried in the pricing table: $0.10 per million input tokens, $0.50 per million output, against $2 and $10 for Sonnet 5.5. That’s not an incremental price cut. That’s a different cost category.
The benchmark jump backs it up. OSWorld 2.1 went from 15.7% on Haiku 4.5 to 72.4% on Haiku 5.5. Terminal-Bench 4.0 went from a flat 0.0% to 39.2%. GDPval-AA, Anthropic’s own benchmark for real professional tasks, moved from 735 Elo to 1620 — roughly double in relative skill terms. Those aren’t rounding errors. They’re the difference between “don’t bother routing agent subtasks here” and “actually consider it.” Anthropic is selling Haiku 5.5 on exactly that pitch: a model cheap enough for high-volume, latency-sensitive work — classification, extraction, routing, subagent calls — that’s now, for the first time, also competent at terminal and computer-use tasks that used to need a bigger model.
I believe the pitch. I don’t believe the headline price cut is the whole story.
The tokenizer tax nobody puts in the announcement
Simon Willison ran the numbers the same day and found something Anthropic’s own page doesn’t mention: Haiku 5.5 uses a new tokenizer, and it’s measurably less efficient. The same long prompt costs around 1.25x the tokens compared to Haiku 4.5. Run that against the headline “around 75% cheaper to run” claim and the real savings on long-context work land closer to 60% than 75%. Still good. Just not the number on the landing page.
This is the part a tech lead actually needs to model before swapping models in a production pipeline: run your own representative prompts through both tokenizers and compare billed tokens, not list price per million. A model that’s 5x cheaper per token but needs 1.25x more tokens for your specific workload isn’t a 5x win. It’s closer to a 4x win. Still worth shipping. Just do the arithmetic with your own prompts, not Anthropic’s marketing prompt.
Reasoning you can’t turn off
The other detail worth flagging: Haiku 5.5 defaults to “medium” reasoning effort, and you cannot disable reasoning entirely. Willison’s pelican-SVG benchmark took 7 seconds and under a tenth of a cent at low effort, and 5 minutes 9 seconds and 3.4 cents at max effort — on the same prompt. For a model marketed on speed and high-volume throughput, that’s a real design tension. If your use case is “classify this support ticket in under 200ms,” test what minimum effort actually costs you in latency and tokens, because the floor isn’t zero.
Available everywhere, which matters more than it sounds
Haiku 5.5 launched simultaneously on Claude’s own platform, AWS Bedrock, Google Cloud Vertex, and Microsoft Foundry. For a cost-tier model specifically, day-one multi-cloud availability matters because this is the model you’ll be calling millions of times. Whatever committed-spend discount you already negotiated on AWS or Azure becomes a real lever here, not a footnote. That’s a different calculus than committing to a frontier reasoning model, where teams will tolerate single-cloud lock-in for the capability. A commodity-tier model shipping everywhere on day one tells you it was built to compete on total cost of ownership — including the contract you already signed — not just price per token on a chart.
Where I’d actually route to it
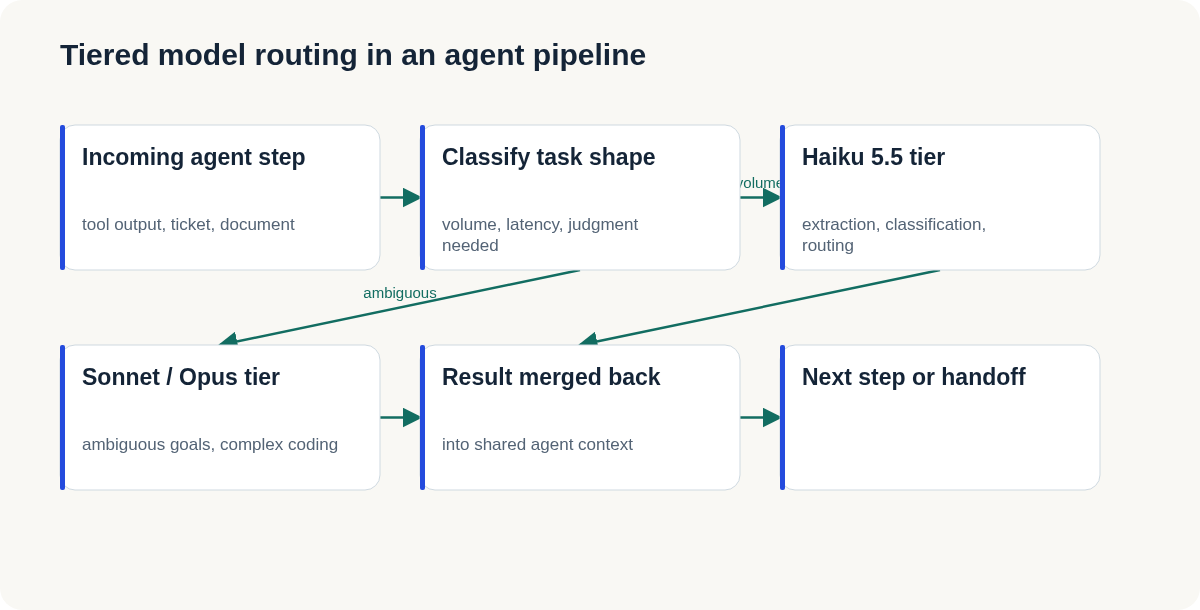
Anthropic’s own docs are honest about the limits here — Sonnet 5.5 and Opus 5.5 “remain better choices for complex agentic coding tasks.” I’d take that at face value. The place Haiku 5.5 earns its price is the boring, high-volume middle of an agent pipeline: summarizing tool output before it hits a bigger model’s context window, classifying which of ten possible next actions a step needs, running the same extraction prompt across ten thousand documents. Not the step where the agent has to decide what to do next with ambiguous instructions.
Asana reported over 30% latency reduction and up to 2.5x faster inference per agent turn after adopting it, and HubSpot scored 92.8% on its own CRM audit task suite with it — both are customer numbers from Anthropic’s page, not independent benchmarks, so treat them as directional rather than proof. But they match the shape of what the pricing and benchmarks suggest: Haiku 5.5 is a genuine upgrade for the parts of your agent architecture that run constantly and don’t need judgment calls.
If you’re building multi-agent systems right now, this is the argument for a tiered-routing layer instead of one model picking up every call: classify the task shape first, then decide whether it needs Haiku’s speed or Sonnet’s judgment. Haiku 5.5 just moved that line further than it’s ever been. It moved it for narrow, well-scoped work — not for everything that used to be too expensive to automate.
Discussion
Comments are reviewed before publication. Your email is kept private.